Pandas
Reshaping Data
Concatenate
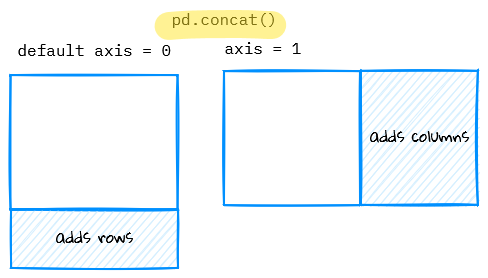
df = pd.concat([df, df1, df2])- add rows / stack verticallydf = pd.concat([df, df1, df2], axis=1)- add columns / place side by side
Dropping columns
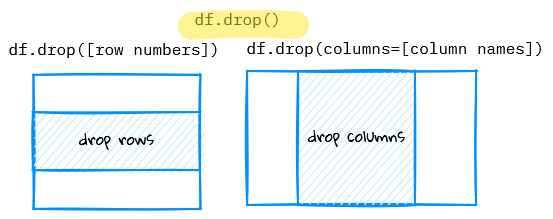
df.drop(columns=column_name)- removes specific columndf.drop(columns=["A","B"])- drops the specified column names from a list
Dropping rows
df.drop(row_label)- removes specific rowdf.drop([0, 1])- drops multiple rows from a listdf.dropna()- drops rows where at least one one element is missingdf.dropna(axis = "columns")- drops the columns where at least one element is missingdf.dropna(subset = ["A", "B"])- identifies a list of columns to be dropped when at least one element in the column is missingdf.dropna(how="all")- drops the rows where all the elements are missingdf.drop_duplicates()- removes duplicate rows based on all columnsdf.drop_duplicates(keep='first')- removes duplicate rows based on all columns, specifying to keep the first occurrencedf.drop_duplicates(subset = ["A", "B"])- removes duplicates on specified columns
Add columns
cols = df1.columns
cols = cols + ["newA", "newB"]

df2 = df1.loc[:, cols]
Transformations
Renaming columns: df.rename(columns= {"from_name": "to_name"})
Group by then sum:
groupby_cols = ["colA", "colB", "colC"]
df["colSum"] = df.groupby_cols["colE"].transform("sum")
df = df[groupby_cols + ["colSum"]].drop_duplicates()
Conditional transformations
Replace values when a condition is satisfied: df = df.where(df>0, other=0)
Note on numpy select vs. where:
Use np.select() when you have multiple conditions and corresponding choices. It also allows specifying a default value when the conditions are not met.
import numpy as np

conditions_list = []
choices_list = []
np.select(conditions_list, choices_list, default)
Use np.where() to replace values based on a single condition. Example: If the value is greater than 20, return 1, otherwise return 0
result = np.where(arr > 20, 1, 0)
Replace specified columns containing null values with 0:
fill_cols = ["colA", "colB", "colC"]
df[fill_cols] = df[fill_cols].fillna(0)
Transform data type: df = df.astype(int)
string replacemnts: ex.
pd.to_numeric(df["A"], errors="coerce")- remove comma and trailing spaces:
df["A"] = df["A"].astype(str).str.replace(",","").str.strip()